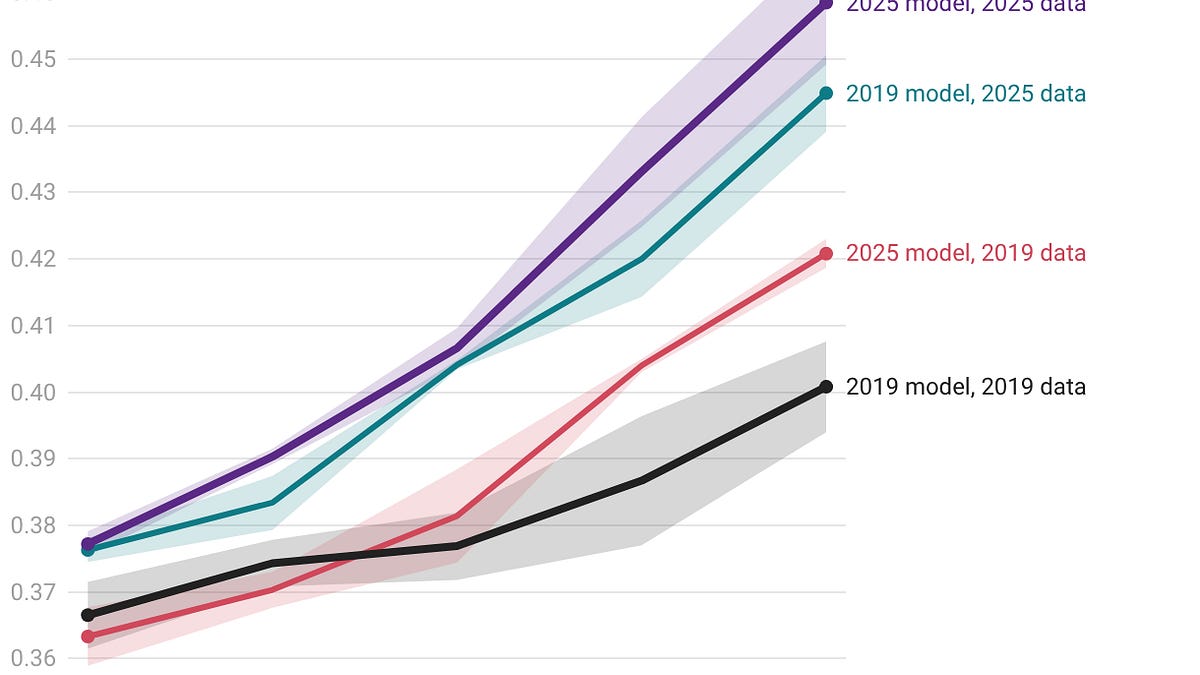
A naive interpretation of our result is that most of the AI progress from 2019-2024 (the era of pretraining) was just better data engineering (extraction, curation, etc.), and that all the model work during that period was much less important. But this is probably the wrong way to think about the value of model improvements. Their main contribution was not necessarily compute efficiency - that is, achieving the same performance with fewer FLOPs. Rather, it was making larger amounts of compute usable in the first place.